Selective visual inference with observable decisions
The descriptor decides whether to look again — and the decision, not only the detection, is what gets recorded.
Real drives from two cars, 236,130 frames: a content-triggered refresh hid 2.01 points fewer scene changes than a timer at the same share of skipped model calls. The decision layer now also runs live on ROS 2 and the Vehicle Signal Specification, and a recorded live run replays to the same decision on every frame.
Vision models are normally run on every frame. That is the safe default and an expensive one. The narrower question is whether a cheap scene descriptor can decide when the previous interpretation still holds, and whether the cost of being wrong about that can be measured rather than assumed.
The first measurement: across 1,712 contiguous dashcam frames at 5 Hz, a class-count descriptor skipped 43.6% of candidate model calls and left 28.5% of material scene changes without refreshed perception. Adding spatial and scale information brought the second figure to 9.1%, and cost reuse to do it. The result worth reporting is not a single optimum but that the tradeoff is measurable, which turns scene representation into an explicit engineering parameter rather than an implementation detail.
A second, independent detector evaluates the same frames, so the measurement does not rest on the detector that also defines the state being evaluated. The two disagreed about the presence of vulnerable road users on 9.5% of frames. Neither is ground truth — both are detectors — so that figure is disagreement, not an error rate, and it is reported as such.
The same measurement then ran at scale on comma2k19, a public set of commuting drives: 94 drives of two cars at 5 Hz, graded by the independent detector. On the 84 drives with complete recordings, refreshing when the content warranted it hid 2.01 percentage points fewer material changes than refreshing on a timer at an equal rate of reuse (95% interval 1.31 to 2.70, resampling whole drives within each car). The analysis was fixed in writing before the last chunk's results existed; on that held-out chunk alone the difference was 3.27 points. The earlier dashcam study reproduces exactly on the new engine, 5,136 of 5,136 decisions.
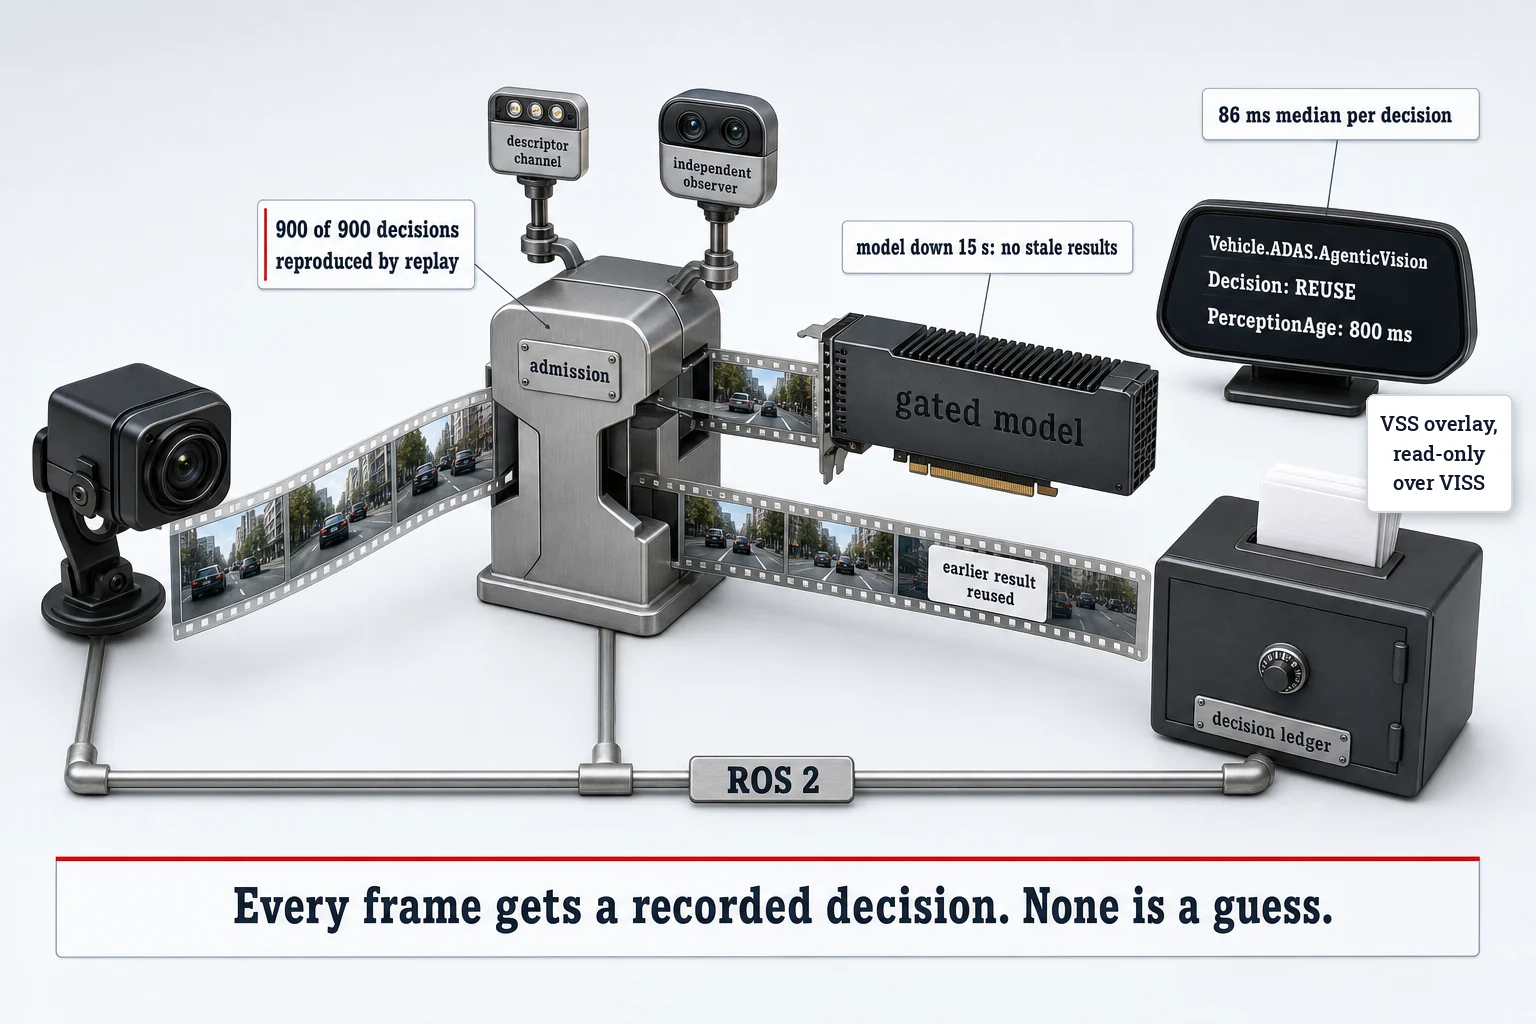
The decision layer also runs live, on the interfaces a vehicle integration uses. A recorded drive plays through ROS 2 in real time, a ROS 2 node decides every frame, the gated model runs on a GPU only for the frames sent to it, and a detector of a different family runs alongside as an independent observer. Each decision is published on ROS 2 and as a read-only overlay in the COVESA Vehicle Signal Specification, read over VISS through an Eclipse KUKSA broker. Over three minutes of driving, replaying the node's recorded inputs reproduces its decision on 900 of 900 frames, four runs agree on every frame, and with the model service down for 15 seconds the 75 affected frames report no perception rather than a stale result. From frame arrival to decision takes 86 ms at the median, inside the 200 ms frame period.
Stated on the site rather than left to be discovered: the replay measurements invoke no vision model; they determine when a call would occur and what deferring it costs. The live stack does call one. Nothing here has been validated for use in a vehicle.
Transferable principle: a cache that hides a state change is not a performance question but a governance one, and the reuse decision has to be observable before anyone can argue about it.
References
- Kang et al. (2017). NoScope: Optimizing neural network queries over video at scale. Proceedings of the VLDB Endowment 10(11), 1586–1597. doi:10.14778/3137628.3137664
- Geifman and El-Yaniv (2017). Selective classification for deep neural networks. NeurIPS 2017. arXiv:1705.08500
- Schafer, Santana, Haden and Biasini (2018). A commute in data: The comma2k19 dataset. arXiv preprint. arXiv:1812.05752
- Zhao et al. (2024). DETRs beat YOLOs on real-time object detection. IEEE/CVF CVPR 2024, 16965–16974. doi:10.1109/CVPR52733.2024.01605